Background Jobs
No one likes waiting in line. This is especially true of your website: users don't want to wait for things to load that don't directly impact the task they're trying to accomplish. For example, sending a "welcome" email when a new user signs up. The process of sending the email could take as long or longer than the sum total of everything else that happens during that request. Why make the user wait for it? As long as they eventually get the email, everything is good.
Concepts
A typical create-user flow could look something like this:
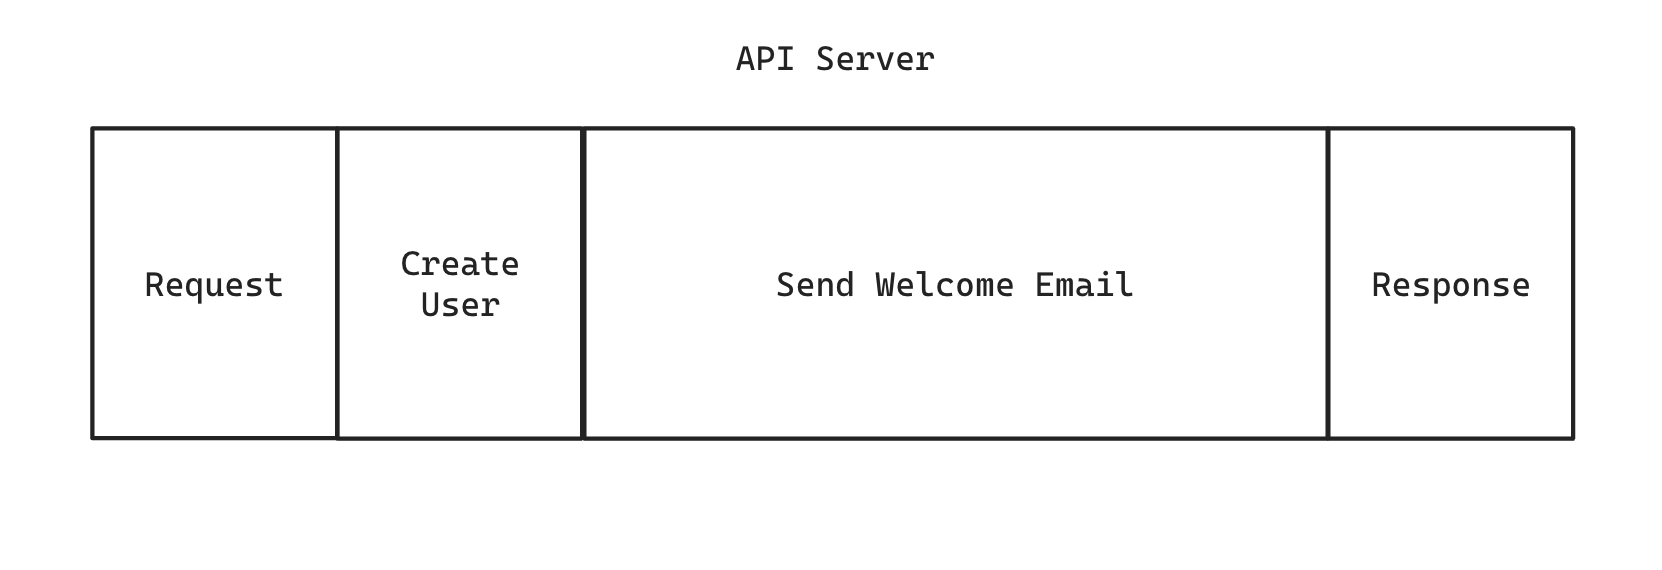
If we want the email to be sent asynchronously, we can shuttle that process off into a background job:
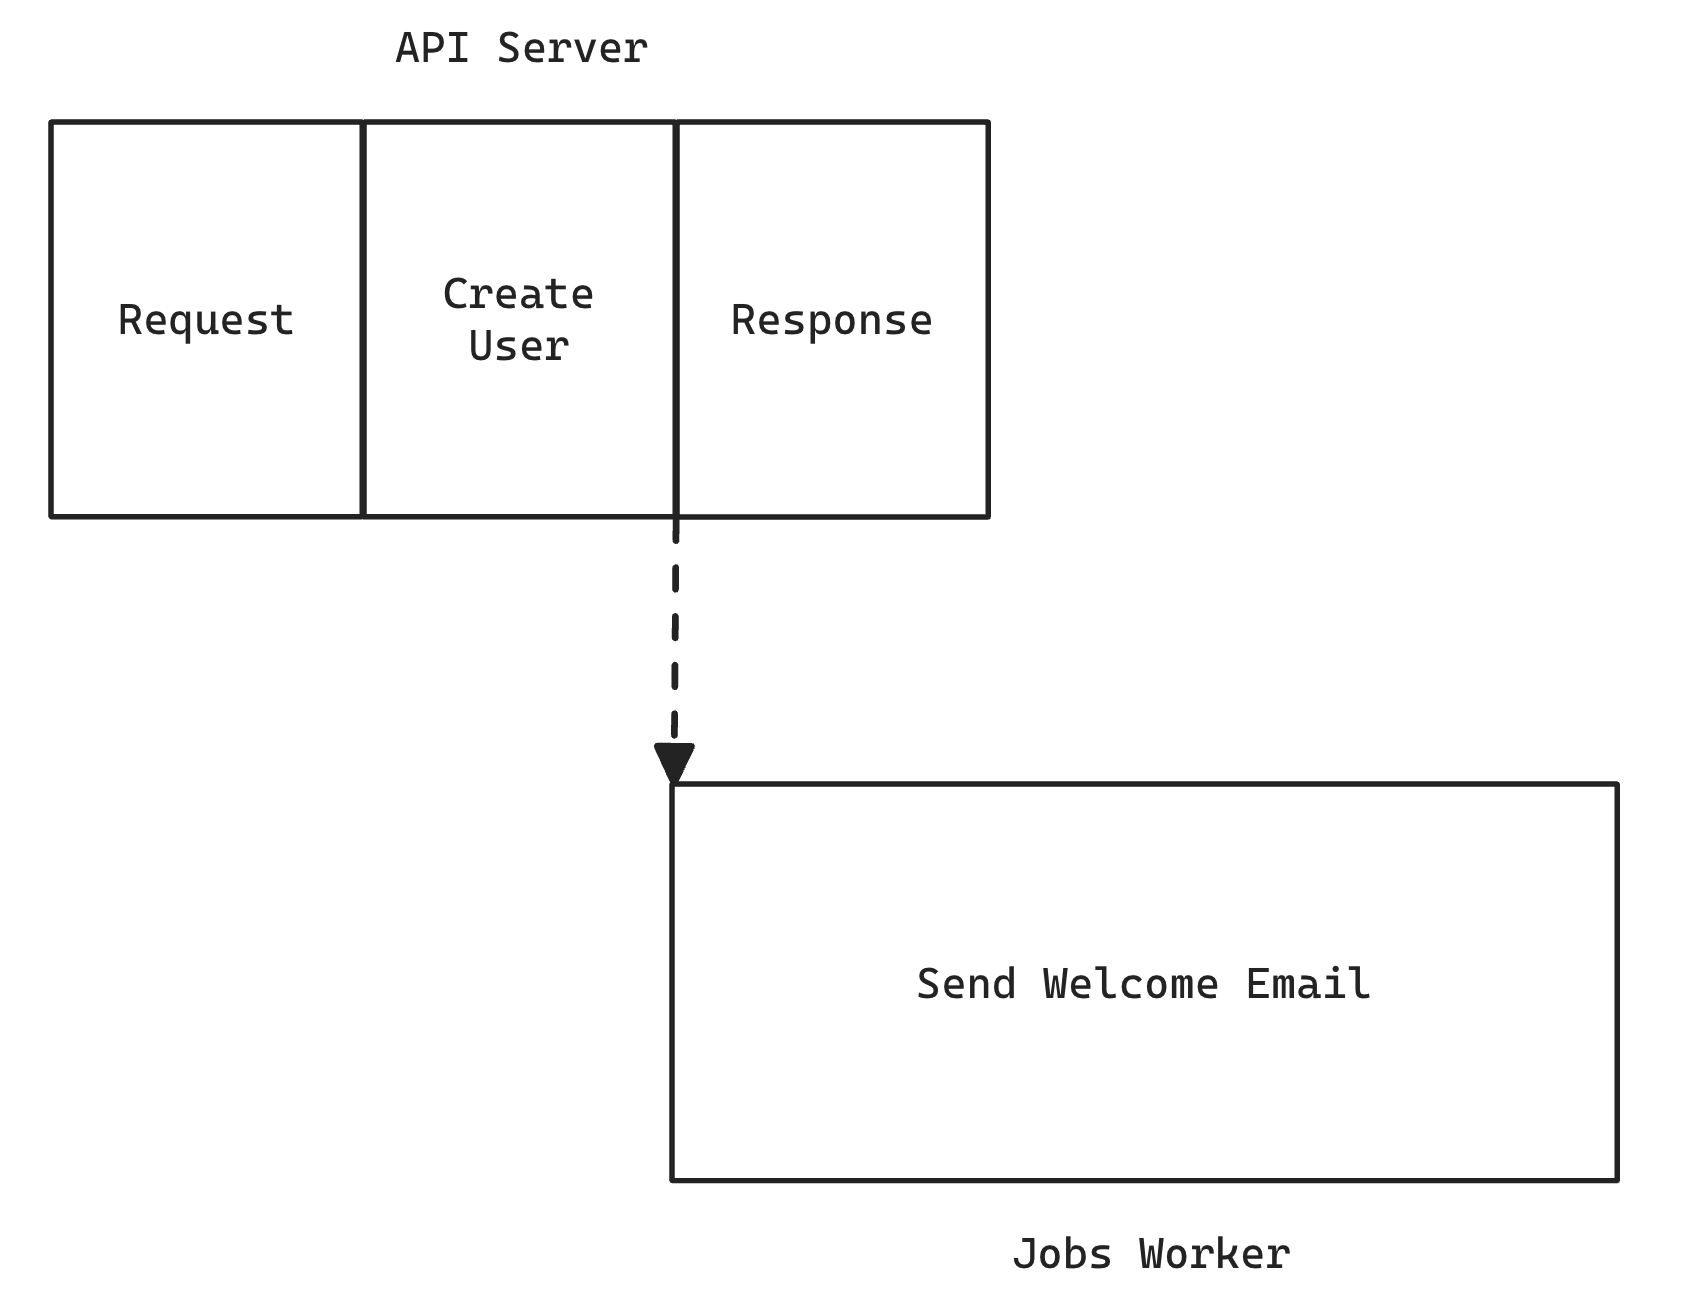
The user's response is returned much quicker, and the email is sent by another process, literally running in the background. All of the logic around sending the email is packaged up as a job and a job worker is responsible for executing it.
Each job is completely self-contained and has everything it needs to perform its own task.
Overview
There are three components to the Background Job system in Cedar:
- Scheduling
- Storage
- Execution
Scheduling is the main interface to background jobs from within your application code. This is where you tell the system to run a job at some point in the future, whether that's:
- as soon as possible
- delay for an amount of time before running
- run at a specific datetime in the future
Storage is necessary so that your jobs are decoupled from your running application. The job system interfaces with storage via an adapter. With the included PrismaAdapter, jobs are stored in your database. This allows you to scale everything independently: the api server (which is scheduling jobs), the database (which is storing the jobs ready to be run), and the job workers (which are executing the jobs).
Execution is handled by a job worker, which takes a job from storage, executes it, and then does something with the result, whether it was a success or failure.
When scheduling a job, you're really saying "this is the earliest possible time I want this job to run": based on what other jobs are in the queue, and how busy the workers are, they may not get a chance to execute this one particular job for an indeterminate amount of time.
The only thing that's guaranteed is that a job won't run any earlier than the time you specify.
Queues
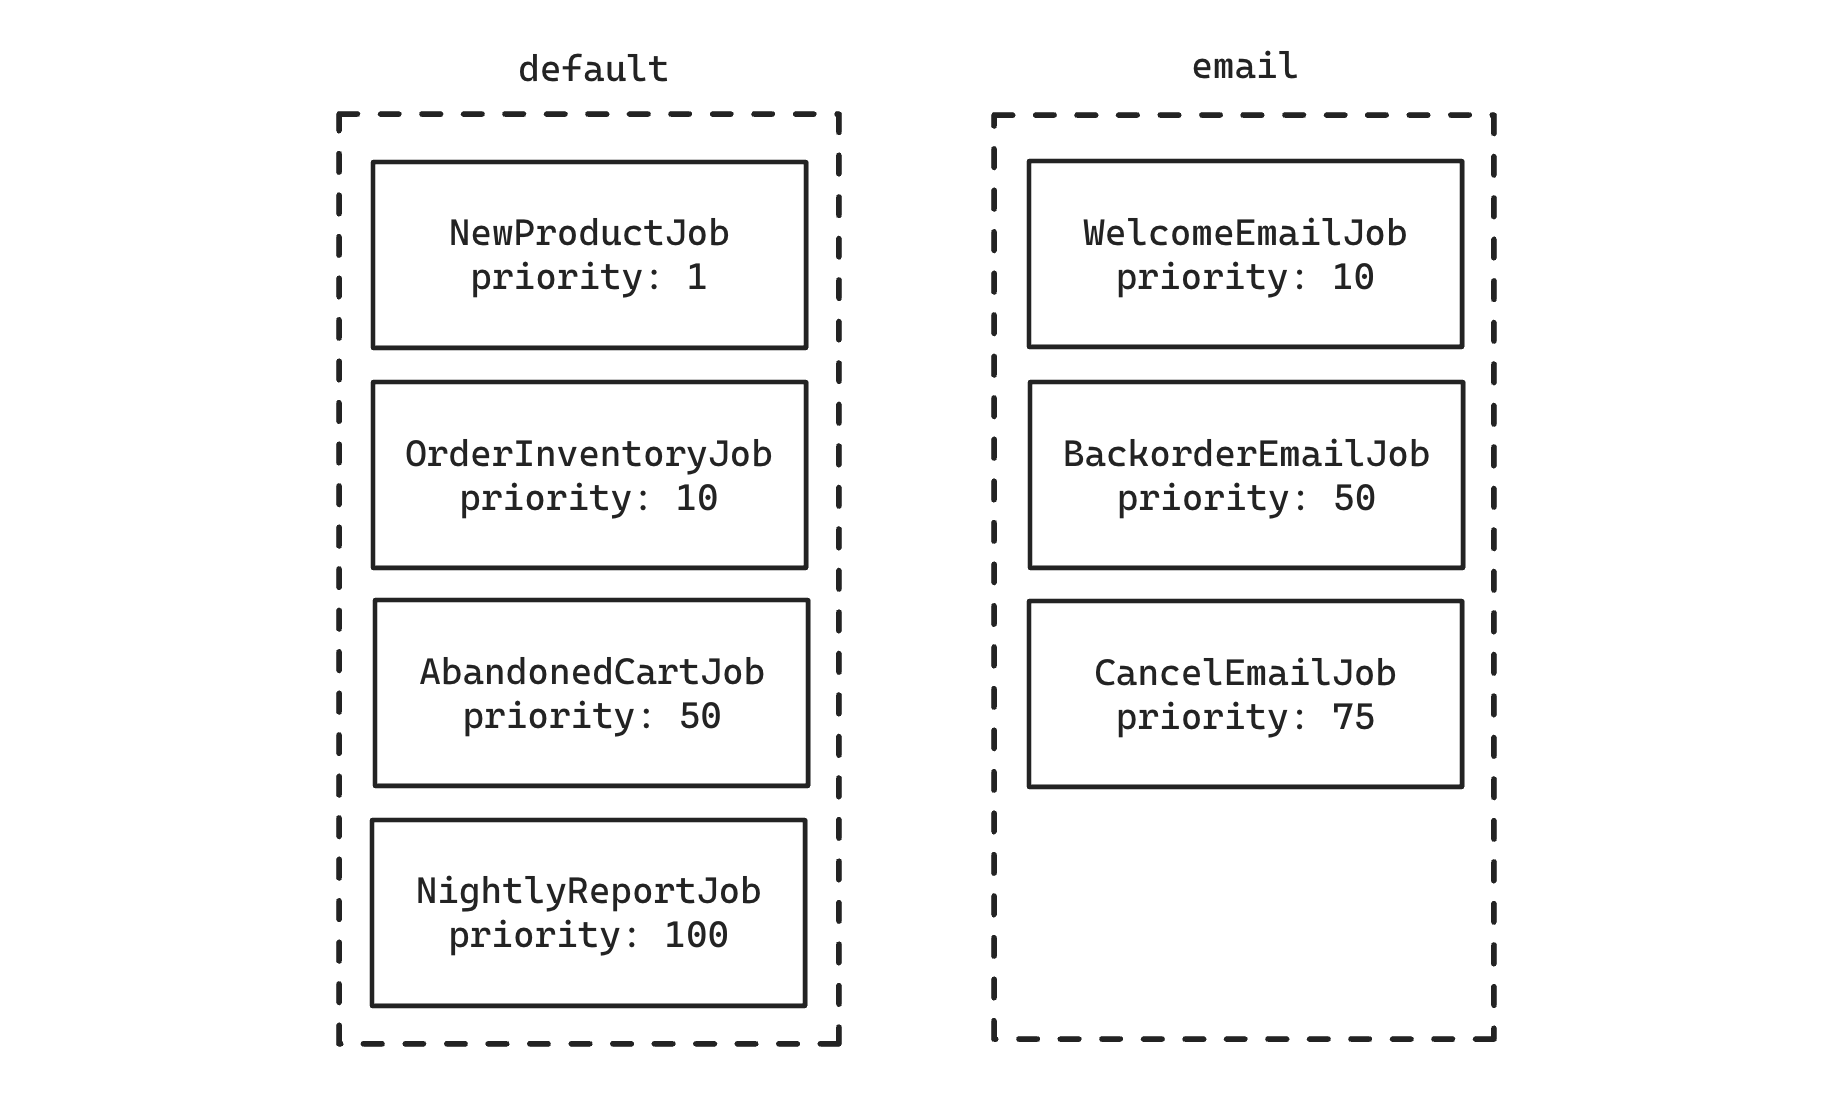
Jobs are organized by a named queue. This is simply a string and has no special significance, other than letting you group jobs. Why group them? So that you can potentially have workers with different configurations working on them. Let's say you send a lot of emails, and you find that among all your other jobs, emails are starting to be noticeably delayed when sending. You can start assigning those jobs to the "email" queue and create a new worker group that only focuses on jobs in that queue so that they're sent in a more timely manner.
Jobs are sorted by priority before being selected to be worked on. Lower numbers mean higher priority:
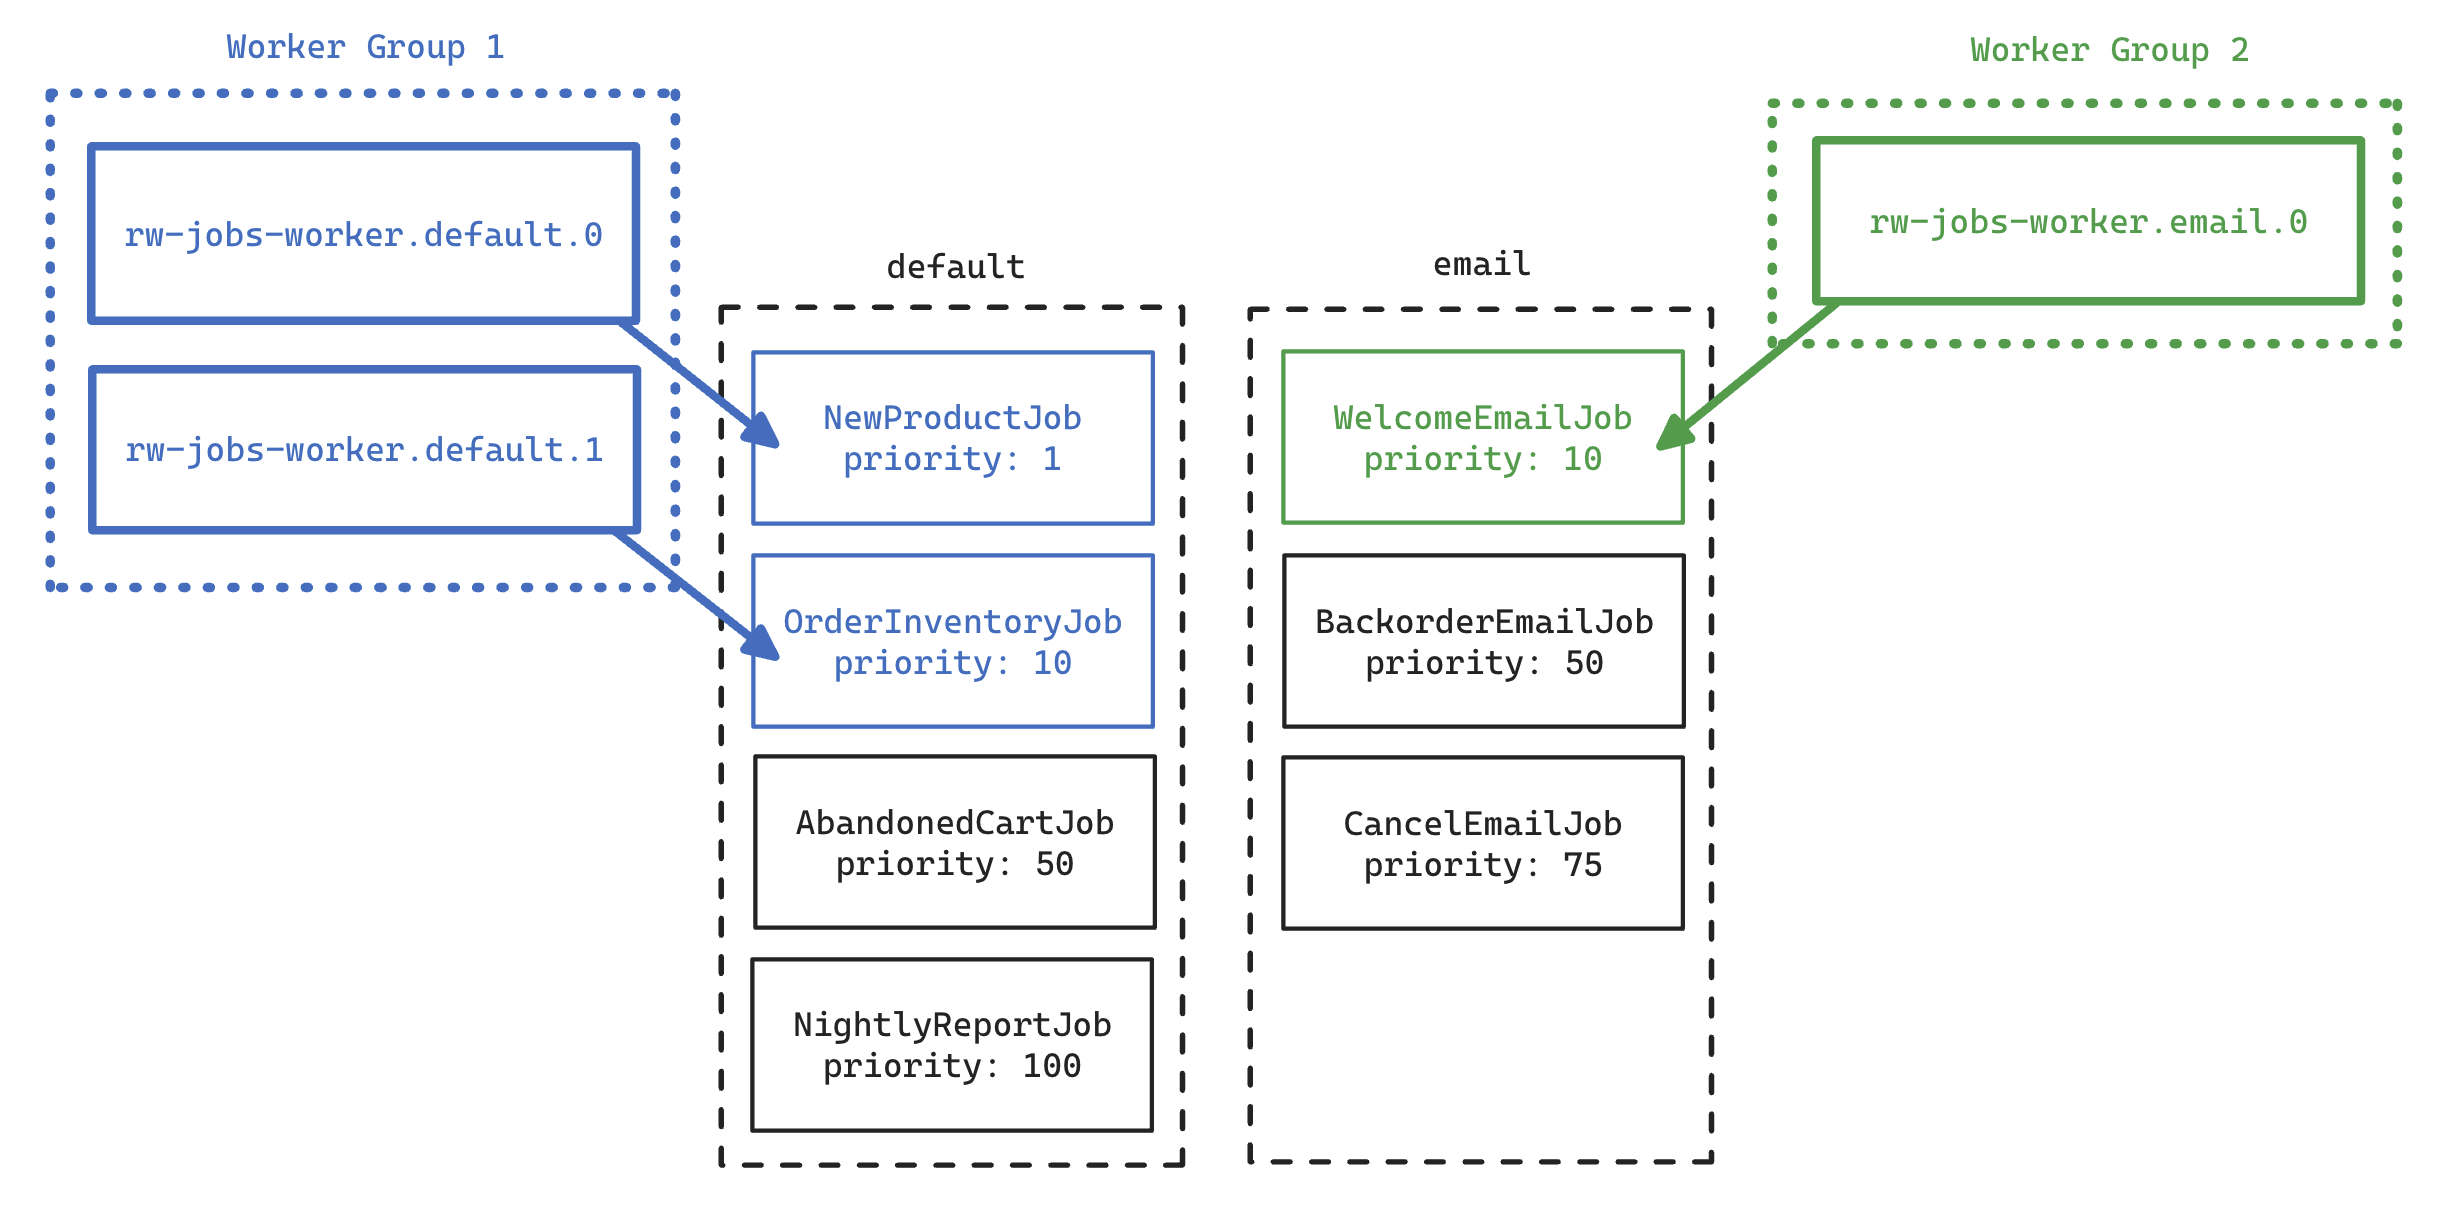
You can also increase the number of workers in a group. If we bumped the group working on the "default" queue to 2 and started our new "email" group with 1 worker, once those workers started we would see them working on the following jobs:
Quick Start
Start here if you want to get up and running with jobs as quickly as possible and worry about the details later.
Setup
Run the setup command to get the jobs configuration file created and migrate the database with a new BackgroundJob table:
yarn cedar setup jobs
yarn cedar prisma migrate dev
This created api/src/lib/jobs.js (or .ts) with a sensible default config. You can leave this as is for now.
Create a Job
yarn cedar g job SampleJob
This created api/src/jobs/SampleJob/SampleJob.js and a test and scenario file. For now the job just outputs a message to the logs, but you'll fill out the perform() function to take any arguments you want and perform any work you want to do. Let's update the job to take a user's id and then just print that to the logs:
import { jobs } from 'src/lib/jobs'

export const SampleJob = jobs.createJob({
  queue: 'default',
  perform: async (userId) => {
    jobs.logger.info(`Received user id ${userId}`)
  },
})
Schedule a Job
You'll most likely be scheduling work as the result of one of your service functions being executed. Let's say we want to schedule our SampleJob whenever a new user is created:
import { db } from 'src/lib/db'
import { later } from 'src/lib/jobs'
import { SampleJob } from 'src/jobs/SampleJob'

export const createUser = async ({ input }) => {
  const user = await db.user.create({ data: input })
  await later(SampleJob, [user.id], { wait: 60 })
  return user
}
The first argument is the job itself, the second argument is an array of all the arguments your job should receive. The job itself defines them as normal, named arguments (like userId), but when you schedule you wrap them in an array (like [user.id]). The third argument is an optional object that provides a couple of options. In this case, the number of seconds to wait before this job will be run (60 seconds).
Executing a Job
Start the worker process to find jobs in the DB and execute them:
yarn cedar jobs work
This process will stay attached to the terminal and show you debug log output as it looks for jobs to run. Note that since we scheduled our job to wait 60 seconds before running, the runner will not find a job to work on right away (unless it's already been a minute since you scheduled it!).
That's the basics of jobs! Keep reading to get a more detailed walkthrough, followed by the API docs listing all the various options. We'll wrap up with a discussion of using jobs in a production environment.
In-Depth Start
Let's go into more depth in each of the parts of the job system.
Installation
To get started with jobs, run the setup command:
yarn cedar setup jobs
This will add a new model to your Prisma schema, and create a configuration file at api/src/lib/jobs.js (or .ts for a TypeScript project). You'll need to run migrations in order to actually create the model in your database:
yarn cedar prisma migrate dev
This added the following model:
model BackgroundJob {
  id        Int       @id @default(autoincrement())
  attempts  Int       @default(0)
  handler   String
  queue     String
  priority  Int
  runAt     DateTime?
  cron      String?
  lockedAt  DateTime?
  lockedBy  String?
  lastError String?
  failedAt  DateTime?
  key       String?   @unique
  pausedAt  DateTime?
  createdAt DateTime  @default(now())
  updatedAt DateTime  @updatedAt
}
key and pausedAt columns to an existing appThe key column stores the keys of unique jobs and of declared schedules, and the pausedAt column stores paused jobs. Apps that set up jobs before these columns existed keep working without them, until they use what needs them:
- Without
key, a keyedlater()call rejects with aSchedulingErrorwhoseoriginalErroris aKeyColumnMissingError, and syncing declared schedules throws aKeyColumnMissingError. - Without
pausedAt, pausing and resuming jobs throw aPausedAtColumnMissingError.
To add them, add key String? @unique and pausedAt DateTime? to your BackgroundJob model and run yarn cedar prisma migrate dev. Both columns are nullable, so existing rows don't need a value.
Let's look at the config file that was generated. Comments have been removed for brevity:
import { PrismaAdapter, JobManager } from '@cedarjs/jobs'

import { db } from 'src/lib/db'
import { logger } from 'src/lib/logger'

export const jobs = new JobManager({
  adapters: {
    prisma: new PrismaAdapter({ db, logger }),
  },
  queues: ['default'],
  logger,
  workers: [
    {
      adapter: 'prisma',
      logger,
      queue: '*',
      count: 1,
      maxAttempts: 24,
      maxRuntime: 14_400,
      deleteFailedJobs: false,
      sleepDelay: 5,
    },
  ],
})

export const later = jobs.createScheduler({
  adapter: 'prisma',
})
Two variables are exported: one is an instance of the JobManager called jobs on which you'll call functions to create jobs and schedulers. The other is later which is an instance of the Scheduler, which is responsible for getting your job into the storage system (out of the box this will be the database thanks to the PrismaAdapter).
We'll go into more detail on this file later (see JobManager Config), but what's there now is fine to get started creating a job.
Creating New Jobs
We have a generator that creates a job in api/src/jobs:
yarn cedar g job SendWelcomeEmail
Jobs are defined as a plain object and given to the createJob() function (which is called on the jobs export in the config file above). An example SendWelcomeEmailJob may look something like:
import { db } from 'src/lib/db'
import { mailer } from 'src/lib/mailer'
import { jobs } from 'src/lib/jobs'

export const SendWelcomeEmailJob = jobs.createJob({
  queue: 'default',
  perform: async (userId) => {
    const user = await db.user.findUnique({ where: { id: userId } })
    await mailer.send(WelcomeEmail({ user }), {
      to: user.email,
      subject: `Welcome to the site!`,
    })
  },
})
At a minimum, a job must contain the name of the queue the job should be saved to, and a function named perform() which contains the logic for your job. You can add additional properties to the object to support the task your job is performing, but perform() is what's invoked by the job worker that we'll see later.
Note that perform() can take any argument(s) you want (or none at all), but it's a best practice to keep them as simple as possible. With the PrismaAdapter the arguments are stored in the database, so the list of arguments must be serializable to and from a string of JSON.
Most jobs will probably act against data in your database, so it makes sense to have the arguments simply be the id of those database records. When the job executes it will look up the full database record and then proceed from there.
If it's likely that the data in the database will change before your job is actually run, but you need the job to run with the original data, you may want to include the original values as arguments to your job. This way the job is sure to be working with those original values and not the potentially changed ones in the database.
Scheduling Jobs
Remember the later export in the jobs config file:
export const later = jobs.createScheduler({
  adapter: 'prisma',
})
You call this function, passing the job, job arguments, and an optional options object when you want to schedule a job. Let's see how we'd schedule our welcome email to go out when a new user is created:
import { later } from 'src/lib/jobs'
import { SendWelcomeEmailJob } from 'src/jobs/SendWelcomeEmailJob'

export const createUser = async ({ input }) {
  const user = await db.user.create({ data: input })
  await later(SendWelcomeEmailJob, [user.id])
  return user
}
By default the job will run as soon as possible. If you wanted to wait five minutes before sending the email you can set a wait time to a number of seconds:
later(SendWelcomeEmailJob, [user.id], { wait: 300 })
Or run it at a specific datetime:
later(MillenniumAnnouncementJob, [user.id], {
  waitUntil: new Date(3000, 0, 1, 0, 0, 0),
})
later() returns whatever the adapter's schedule() function returns. For the PrismaAdapter that's the job record that was created in the database, so you can hold on to its id to check on the job later, or to cancel it:
const scheduledJob = await later(SendWelcomeEmailJob, [user.id])
// scheduledJob.id can be used with `later.cancel()`
If we were to query the BackgroundJob table after the job has been scheduled you'd see a new row. We can use the Cedar Console to query the table from the command line:
% yarn cedar console
> db.backgroundJob.findMany()
[
  {
    id: 1,
    attempts: 0,
    handler: '{"name":"SendWelcomeEmailJob",path:"SendWelcomeEmailJob/SendWelcomeEmailJob","args":[335]}',
    queue: 'default',
    priority: 50,
    runAt: 2024-07-12T22:27:51.085Z,
    lockedAt: null,
    lockedBy: null,
    lastError: null,
    failedAt: null,
    createdAt: 2024-07-12T22:27:51.125Z,
    updatedAt: 2024-07-12T22:27:51.125Z
  }
]
Because we're using the PrismaAdapter here all jobs are stored in the database, but if you were using a different storage mechanism via a different adapter you would have to query those in a manner specific to that adapter's backend.
The handler column contains the name of the job, file path to find it, and the arguments its perform() function will receive. Where did the name and path come from? We have a babel plugin that adds them to your job when they are built!
Jobs are run from the api/dist directory, which will exist only after running yarn cedar build api or yarn cedar dev. If you are working on a job in development, you're probably running yarn cedar dev anyway. But just be aware that if the dev server is not running then any changes to your job will not be reflected unless you run yarn cedar build api (or start the dev server) to compile your job into api/dist.
Cancelling Jobs
Sometimes you schedule a job and then change your mind—maybe the user deleted the record the job was going to work on, or an admin wants to stop an expensive job that's no longer needed. Use later.cancel(), passing the id of the job that later() returned:
import { later } from 'src/lib/jobs'
import { SendWelcomeEmailJob } from 'src/jobs/SendWelcomeEmailJob'

const scheduledJob = await later(SendWelcomeEmailJob, [user.id])

// somewhere else, later on
await later.cancel(scheduledJob.id)
later.cancel() returns true if a job was cancelled and false if no cancellable job with that id was found (it may have already completed, or already failed).
What cancelling means depends on the state of the job:
- Queued, not started yet: the job will never run. Using the
PrismaAdapterthe job stays in the database marked as failed (failedAtis set andlastErroris"Job cancelled by user") so you keep a record of it. - Currently running: the in-progress attempt is not interrupted (see Job Timeouts—the worker will stop waiting on it once
maxRuntimeis exceeded), but the job will not be retried if it errors, and no other worker will pick it up. Even if the in-progress attempt finishes successfully, the job record keeps its cancelled state (it won't be deleted bydeleteSuccessfulJobs).
Cancellation requires an adapter that implements the optional cancel() function. The PrismaAdapter does; for a custom adapter that doesn't, later.cancel() throws a CancelNotImplementedError.
Unique Jobs
Sometimes the same work gets requested many times in a row: every time someone opens a page you want to refresh its thumbnails, but one refresh that's still waiting to run covers all of those requests. Give the job a key and only one job with that key will be queued at a time:
const job = await later(RefreshThumbnailsJob, [page.id], {
  key: `thumbnails:${page.id}`,
  wait: 30,
})

if (job.alreadyQueued) {
  // A job with this key was already waiting to run. No new job was added,
  // and `job` is the one that's queued
}
What "already queued" means, exactly:
- A job holds its key from when it's scheduled until a worker picks it up. While it's waiting to run, scheduling another job with the same key adds nothing and returns the queued job, with
alreadyQueued: true. - Once a worker has picked the job up, the key is free: a new job with the same key can be queued while the first one runs. Work requested while the job runs may need another run, so it isn't skipped. The same goes for a job that's waiting to be retried after an error, and for a cancelled job.
- Only the key is compared. The queued job keeps its own arguments and run time, and the
waityou pass for the skipped job is ignored. Put whatever must be distinct into the key, like the record's id above. - A recurring (
cron) job scheduled with a key holds it for as long as its schedule is active, solater(NightlyReportJob, { cron: '0 0 * * *', key: 'nightly-report' })is safe to run more than once. - The guarantee comes from the database: the
keycolumn is@unique, so it holds when several processes schedule the same key at the same time.
Keys starting with cedar: are reserved for Cedar's own keys. Unique keys need the key column and an adapter that supports them, like the PrismaAdapter; with an adapter that doesn't, scheduling with a key throws a UniqueKeysNotSupportedError.
Long Jobs That Continue Later
A worker runs one job at a time, so a job that runs for a long time keeps every job behind it on the same queue waiting. If a job works through a long list, have it stop after a time budget and queue its own continuation, so other jobs get their turn in between:
const BUDGET_MS = 45_000

export const ProcessImportJob = jobs.createJob({
  queue: 'default',
  perform: async (importId, afterId = null) => {
    const deadline = Date.now() + BUDGET_MS
    const rows = await db.importRow.findMany({
      where: { importId, id: afterId ? { gt: afterId } : undefined },
      orderBy: { id: 'asc' },
    })

    for (const row of rows) {
      if (Date.now() >= deadline) {
        // Pick up after the last row this run finished
        await later(ProcessImportJob, [importId, afterId])
        return
      }

      await processRow(row)
      afterId = row.id
    }
  },
})
Pass the continuation where to start (like afterId above) so it doesn't redo work, and keep the budget well below the worker's maxRuntime. More workers for the queue also help, see Multiple Workers.
Pausing Jobs
To stop a job from running for a while without changing your code or deploying, for example to stop a nightly job during an incident, pause it. Find its id with yarn cedar jobs list:
ID  JOB               QUEUE    CRON       STATUS
17  SendDigestJob     default  -          next run 2026-10-12T13:05:00.000Z
3   NightlyReportJob  default  0 0 * * *  next run 2026-10-13T00:00:00.000Z
Then pause it, and resume it when you're ready:
yarn cedar jobs pause 3
yarn cedar jobs resume 3
The same is available in code, on the JobManager:
import { jobs } from 'src/lib/jobs'

const { alreadyPaused, pausedAt } = await jobs.pauseJob(3)
const { wasPaused, runAt } = await jobs.resumeJob(3)
const waiting = await jobs.listJobs({ limit: 20 })
How a pause behaves:
- Workers don't pick up a paused job. A run that's in progress when you pause finishes, and if the job is recurring its next run stays paused. A run that fails and is retried stays paused too. If the worker running a paused job crashes, the job stays locked; once you resume it, any worker picks it up after
maxRuntime(plus a one-minute grace period) has passed since it was locked. - Resuming a recurring job schedules its next run at the next time its
cronmatches from now. Runs it missed while it was paused are not made up for. - Resuming a one-off job keeps its run time: if that's still in the future it runs then, and if it passed while the job was paused it runs as soon as a worker is free.
- When a worker starts (
yarn cedar jobs workorstart, notworkoff), it logs a warning listing the paused jobs in its queues, so a forgotten pause shows up. - Pausing a paused job, or resuming one that isn't paused, changes nothing and says so. Jobs that have completed or failed for good (including cancelled ones) can't be paused or resumed.
yarn cedar jobs listlists the jobs that are waiting to run, running or paused, the ones that run next first, 100 at most (--limitchanges that). If yourJobManagerhas several adapters, pass--adapterto these commands (or{ adapter }to the functions). Likeyarn cedar jobs work, the commands load your jobs config from the built api side.
The pause is stored on the job's row in the database, so it holds across worker restarts and deploys. But if your code deletes and recreates its recurring jobs, like a script that schedules them again on every deploy, the new rows aren't paused. Pause again after such a script runs, or don't run it while a job should stay paused. Declared schedules keep their rows across deploys: a sync updates a paused schedule's cron, arguments, queue and priority, and it stays paused.
Pausing requires an adapter that implements the optional pause() and resume() functions (and list() for listing), like the PrismaAdapter, and the pausedAt column. With an adapter that doesn't, they throw a PauseNotImplementedError.
Executing Jobs
In development you can start a job worker via the job runner from the command line:
yarn cedar jobs work
The runner is a sort of overseer that doesn't do any work itself, but spawns workers to actually execute the jobs. When starting in work mode your workers config will be used to start the workers and they will stay attached to the terminal, updating you on the status of what they're doing:
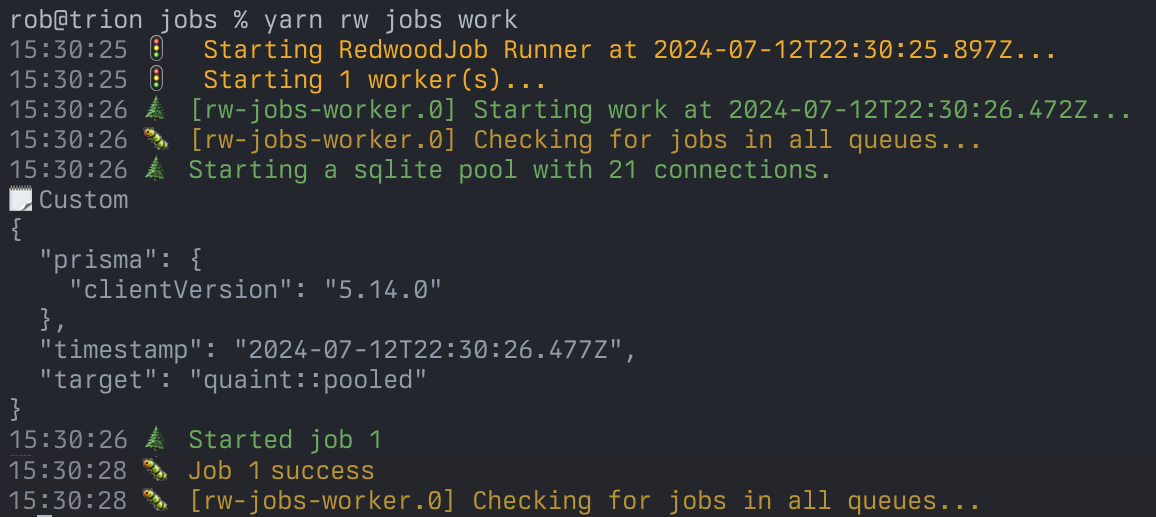
It checks the BackgroundJob table every few seconds for a new job and, if it finds one, locks it so that no other workers can have it, then calls your perform() function, passing it the arguments you gave when you scheduled it.
If the job succeeds then by default it's removed from the database (using the PrismaAdapter, other adapters behavior may vary). If the job fails, the job is un-locked in the database, the runAt is set to an incremental backoff time in the future, and lastError is updated with the error that occurred. The job will now be picked up in the future once the runAt time has passed and it'll try again.
To stop the runner (and the workers it started), press Ctrl-C (or send SIGINT). The workers will gracefully shut down, waiting for their work to complete before exiting. If you don't wait to wait, hit Ctrl-C again (or send SIGTERM).
There are a couple of additional modes that rw jobs can run in:
yarn cedar jobs workoff
This mode will execute all jobs that are eligible to run, then stop itself.
yarn cedar jobs start
Starts the workers and then detaches them to run forever. Use yarn cedar jobs stop to stop them, or yarn cedar jobs restart to pick up any code changes to your jobs.
Everything Else
The rest of this doc describes more advanced usage, like:
- Assigning jobs to named queues
- Setting a priority so that some jobs always run before others
- Using different adapters and loggers on a per-job basis
- Starting more than one worker
- Having some workers focus on only certain queues
- Configuring individual workers to use different adapters
- Manually start workers without the job runner monitoring them
- And more!
Instantly Running Jobs
As noted in the Concepts section, a job is never guaranteed to run at an exact time. The worker could be busy working on other jobs and can't get to yours just yet.
If you absolutely, positively need your job to run right now (with the knowledge that the user will be waiting for it to complete) you can call your job's perform function directly in your code:
await SampleEmailJob.perform(user.id)
Recurring Jobs
A common task for a background job is that it does something on a schedule: run reports every night at midnight, check for abandoned carts every 15 minutes, that sort of thing. We call these recurring jobs.
Declaring Schedules
Declare when a job runs with schedules, next to the rest of the job:
export const NightlyReportJob = jobs.createJob({
  queue: 'default',
  schedules: [{ cron: '0 0 * * *' }],
  perform: async () => {
    // ...
  },
})
That's all: every job worker syncs the declared schedules when it starts. A schedule that isn't stored yet is added, a changed one is updated, and a stored schedule that's no longer declared (because you removed it, or the whole job) is removed. Deploying restarts the workers, so schedules follow your code on every deploy without a script to remember. yarn cedar jobs workoff and clear don't sync.
A job can run on several schedules, with different arguments. Give each schedule a key to tell them apart:
export const ThumbnailsJob = jobs.createJob({
  queue: 'default',
  schedules: [
    // Recent pages often during the day
    { key: 'day', cron: '*/15 * * * *', args: [{ days: 1 }] },
    // Everything from the last two weeks once a night
    { key: 'night', cron: '45 4 * * *', args: [{ days: 14 }] },
  ],
  perform: async ({ days }: { days: number }) => {
    // ...
  },
})
A schedule's identity is the job's name and the schedule's key (which can be left out when the job has a single schedule). Changing a schedule's cron or args updates it in place, changing its key replaces it. In TypeScript, each schedule's args are type checked against perform()'s parameters.
Some details worth knowing:
- Schedules are declared in code, so they can differ between environments like any other code:
cron: process.env.SYNC_CRON ?? '*/5 * * * *', orschedules: process.env.REPORTS_ENABLED ? [...] : []. Each environment's workers sync their own database. - Every worker process syncs, and several syncing at once is safe: each schedule is one row with a unique key, so no duplicates are created. During a rolling deploy the workers started last decide what's stored.
- The sync removes every declared schedule it doesn't find in your code, so it assumes one app per jobs table. A sync imports every module in your jobs directory to find the schedules. If a module fails to import, or a declaration is invalid (a bad cron expression, two schedules with the same key, several schedules without keys), the sync throws and the worker doesn't start, rather than silently running without a schedule.
- Declared schedules need an adapter that implements
syncSchedules(), like thePrismaAdapter, and thekeycolumn. If yourJobManagerhas more than one adapter, setscheduleAdapterto the one that stores them. - A declared schedule that fails
maxAttemptstimes in a row, or that you cancel withlater.cancel(), stops until the next time the workers start, which recreates it.
Schedules That Depend on Your Data
Some schedules come from your data rather than your code, like a digest that each customer gets at a time they pick. Store that schedule with the data, and declare one job that runs often and queues the work that's due:
import { DigestJob } from 'src/jobs/DigestJob/DigestJob'
import { db } from 'src/lib/db'
import { jobs, later } from 'src/lib/jobs'

export const QueueDigestsJob = jobs.createJob({
  queue: 'default',
  schedules: [{ cron: '*/15 * * * *' }],
  perform: async () => {
    const due = await db.customer.findMany({
      where: { nextDigestAt: { lte: new Date() } },
      select: { id: true },
    })

    for (const customer of due) {
      await later(DigestJob, [customer.id], { key: `digest:${customer.id}` })
    }
  },
})
DigestJob sends the digest and sets the customer's nextDigestAt to the next time it's due. Changing when a customer gets their digest is an update to that column, and turning it off is setting it to null. The key makes sure a customer's digest isn't queued again while one is still waiting to run.
Scheduling a Recurring Job with later()
later() also takes a cron schedule, which stores a recurring job directly:
await later(NightlyReportJob, { cron: '0 0 * * *' })
A job scheduled like this isn't synced with your code: it runs until it fails for good or you cancel it, and calling later() again adds a second one unless you give it a key.
If you schedule recurring jobs with a script that calls later(job, args, { cron }), declare them with schedules instead and delete the rows that script created (they have a cron and no key) once, for example with db.backgroundJob.deleteMany({ where: { cron: { not: null }, key: null } }) in yarn cedar console.
How Recurring Jobs Run
Scheduling a recurring job doesn't run it right away. Its first run happens the
next time the cron schedule matches (midnight, for NightlyReportJob above), and
after each successful run the job is scheduled again for the following match. If
a run fails, the job is retried after a backoff delay, like any other job,
rather than at the next match. Matches of the schedule that pass while a run is
being retried are skipped.
For a recurring job, attempts and maxAttempts count consecutive failures of
a single run: every successful run resets attempts to 0. If a run fails
maxAttempts times in a row, or a run exceeds maxRuntime, the job is
permanently failed like any other job, its schedule stops, and the worker logs
an error saying so. To restart the schedule, fix the problem and restart the
workers (for a declared schedule) or call later() with the cron schedule
again.
The cron schedule is evaluated in the local time zone of the process doing the
scheduling: the job worker for declared schedules, the process calling later()
for the first run of a job it schedules, and the job worker for every run
after that. Run them with the same time zone (for example by setting TZ=UTC)
so the job keeps running at the same time of day.
CedarJS uses https://github.com/harrisiirak/cron-parser under the hood for
parsing the cron schedule. So all the syntax supported by cron-parser is
supported. Including, for example, the six-groups format for seconds, and their
predefined expressions
like @hourly, @daily, @weekends, etc. So NightlyReportJob's schedule
could also have been written as cron: '0 0 0 * * *' and cron: '@daily'.
When you schedule recurring jobs you can only specify the cron option. Other
options, like wait or waitUntil, are not supported. These options don't make
sense for recurring jobs because they are scheduled automatically according to
the given schedule.
Configuration
There are a bunch of ways to customize your jobs and the workers.
JobManager Config
Let's take a closer look at the jobs export in api/src/lib/jobs.js:
export const jobs = new JobManager({
  adapters: {
    prisma: new PrismaAdapter({ db, logger }),
  },
  queues: ['default'],
  logger,
  workers: [
    {
      adapter: 'prisma',
      logger,
      queue: '*',
      count: 1,
      maxAttempts: 24,
      maxRuntime: 14_400,
      deleteFailedJobs: false,
      sleepDelay: 5,
    },
  ],
})
The object passed here contains all of the configuration for the Background Job system. Let's take a quick look at the four top-level properties and then we'll get into more details in the subsections to follow.
adapters
This is the list of adapters that are available to handle storing and retrieving your jobs to and from the storage system. You could list more than one adapter here and then have multiple schedulers. Most folks will probably stick with a single one.
queues
An array of available queue names that jobs can be placed in. By default, a single queue named "default" is listed here, and will also be the default queue for generated jobs. To denote the named queue that a worker will look at, there is a matching queue property on the workers config below.
logger
The logger object for all internal logging of the job system itself and will fall back to console if you don't set it.
workers
This is an array of objects, each defining a "group" of workers. When will you need more than one group? If you need workers to work on different queues, or use different adapters. Read more about this in the Job Workers section.
scheduleAdapter
The name of the adapter that stores the schedules jobs declare (see Recurring Jobs). It can be left out when you have a single adapter, or when no job declares schedules.
Adapter Config
Adapters are added as key/value pairs to the adapters object given to the JobManager upon initialization. The key of the property (like prisma in the example below) is the name you'll use in your scheduler when you tell it which adapter to use to schedule your jobs. Adapters accept an object of options when they are initialized.
PrismaAdapter
export const jobs = new JobManager({
  adapters: {
    prisma: new PrismaAdapter({ db, model: 'BackgroundJob', logger }),
  },
  // remaining config...
})
db: [required] an instance ofPrismaClientthat the adapter will use to store, find and update the status of jobs. In most cases this will be thedbvariable exported fromapi/src/lib/db.ts. This must be set in order for the adapter to be initialized!model: the name of the model that was created to store jobs. This defaults toBackgroundJob.logger: events that occur within the adapter will be logged using this. This defaults toconsolebut theloggerexported fromapi/src/lib/loggerworks great.
Scheduler Config
When you create an instance of the scheduler you can pass it a couple of options:
export const later = jobs.createScheduler({
  adapter: 'prisma',
})
adapter: [required] the name of the adapter this scheduler will use to schedule jobs. Must be one of the keys that you gave to theadaptersoption on the JobManager itself.logger: the logger to use for this instance of the scheduler. If not provided, defaults to theloggerset on theJobManager.
Scheduling Options
When using the scheduler to schedule a job you can pass options in an optional third argument:
later(SampleJob, [user.id], { wait: 300 })
wait: number of seconds to wait before the job will runwaitUntil: a specificDatein the future to run atcron: a schedule to run the job on, again and again (see Recurring Jobs)key: makes the job unique while it's queued (see Unique Jobs)
If you don't pass any options then the job will be defaulted to run as soon as possible, ie: new Date()
Job Config
There are three configuration options you can define in the object that describes your job:
import { jobs } from 'src/lib/jobs'

export const SendWelcomeEmailJob = jobs.createJob({
  queue: 'email',
  priority: 1,
  perform: async (userId) => {
    // job details...
  },
})
queue: [required] the name of the queue that this job will be placed in. Must be one of the strings you assigned to thequeuesarray when you set up theJobManager.schedules: the recurring schedules the job runs on, each with acronexpression, theargsto run with and, if the job has more than one, akey. See Recurring Jobs.priority: within a queue you can have jobs that are more or less important. The workers will pull jobs off the queue with a higher priority before working on ones with a lower priority. A lower number is higher in priority than a higher number. Ie. the workers will work on a job with a priority of1before they work on one with a priority of100. If you don't override it here, the default priority is50.
Worker Config
This is the largest section of the JobManager config object. This options array tell the workers how to behave when looking for and executing jobs.
export const jobs = new JobManager({
  // .. more config
  workers: [
    {
      adapter: 'prisma',
      logger,
      queue: '*',
      count: 1,
      maxAttempts: 24,
      maxRuntime: 14_400,
      deleteFailedJobs: true,
      deleteSuccessfulJobs: false,
      sleepDelay: 5,
    },
  ],
This is an array of objects. Each object represents the config for a single "group" of workers. By default, there is only one worker group. It uses the PrismaAdapter and will look for jobs in all queues. If you want to start fine tuning your workers by working with different adapters, or only working on some named queues, you can add additional members to this array, each with a unique set of options.
adapter: [required] the name of the adapter this worker group will use. Must be one of the keys that you gave to theadaptersoption on theJobManageritself.logger: the logger to use when working on jobs. If not provided, defaults to theloggerset on theJobManager. You can use this logger in theperform()function of your job by accessingjobs.logger- queue: [required] the named queue(s) in which this worker group will watch for jobs. There is a reserved
'*'value you can use which means "all queues." This can be an array of queues as well:['default', 'email']for example. count: [required] the number of workers to start with this config.maxAttempts: the maximum number of times to retry a job before giving up. A job that throws an error will be set to retry in the future with a backoff of (number of previous attempts) ** 4 seconds, capped at 7 days. After this number, a job is considered "failed" and will not be re-attempted. For recurring jobs this counts consecutive failures of a single run. Default:24.maxRuntime: the maximum amount of time, in seconds, that a job is allowed to run. A job that runs longer than this is marked as failed (it will not be retried, and the timeout is recorded inlastError) and the worker moves on to the next job. The job is told to stop what it's doing via anAbortSignal—see Job timeouts. This is also how long a job's lock is honored if the worker that locked it crashed without cleaning up after itself: oncemaxRuntime(plus a one-minute grace period, so a live worker always gets to record the timeout first) has passed, another worker is allowed to pick the job up again. Default:14_400(4 hours).deleteFailedJobs: when a job has failed (maximum number of retries has occurred) you can keep the job in the database, or delete it. Default:false.deleteSuccessfulJobs: when a job has succeeded, you can keep the job in the database, or delete it. It's generally assumed that your jobs will succeed so it usually makes sense to clear them out and keep the queue lean. Default:true.sleepDelay: the amount of time, in seconds, to wait before checking the queue for another job to run. Too low and you'll be thrashing your storage system looking for jobs, too high and you start to have a long delay before any job is run. Default:5.
See the next section for advanced usage examples, like multiple worker groups.
Job Workers
A job worker actually executes your jobs. The workers will ask the adapter to find a job to work on. The adapter will mark the job as locked (the worker's lock name and a timestamp are set on the job: the lock name is the process title plus the host name and process id, like cedar-jobs-worker.default.0 host:app-1 pid:4242, so no two running workers share one) and then the worker will call perform() on your job, passing in any args that were given when you scheduled it. The behavior of what happens when the job succeeds or fails depends on the config options you set in the JobManager. By default, successful jobs are removed from storage and failed jobs and kept around so you can diagnose what happened.
The runner has several modes it can start in depending on how you want it to behave.
Dev Modes
These modes are ideal when you're creating a job and want to be sure it runs correctly while developing. You could also use this in production if you wanted (maybe a job is failing and you want to watch verbose logs and see what's happening).
yarn cedar jobs work
This process will stay attached to the console and continually look for new jobs and execute them as they are found. The log level is set to debug by default so you'll see everything. Pressing Ctrl-C to cancel the process (sending SIGINT) will start a graceful shutdown: the workers will complete any work they're in the middle of before exiting. To cancel immediately, hit Ctrl-C again (or send SIGTERM) and they'll stop in the middle of what they're doing. Note that this could leave locked jobs in the database. They'll be picked up again once maxRuntime (plus a one-minute grace period) has expired, even though they are still locked.
To work on whatever outstanding jobs there are and then automatically exit use the workoff mode:
yarn cedar jobs workoff
As soon as there are no more jobs to be executed (either the store is empty, or they are scheduled in the future) the process will automatically exit.
Clearing the Job Queue
You can remove all jobs from storage with:
yarn cedar jobs clear
Production Modes
In production you'll want your job workers running forever in the background. For that, use the start mode:
yarn cedar jobs start
That will start a number of workers determined by the workers config on the JobManager and then detach them from the console. If you care about the output of that worker then you'll want to have configured a logger that writes to the filesystem or sends to a third party log aggregator.
To stop the workers:
yarn cedar jobs stop
Or to restart any that are already running:
yarn cedar jobs restart
Multiple Workers
With the default configuration options generated with the yarn cedar setup jobs command you'll have one worker group. If you simply want more workers that use the same adapter and queue settings, increase the count:
export const jobs = new JobManager({
  adapters: {
    prisma: new PrismaAdapter({ db, logger }),
  },
  queues: ['default'],
  logger,
  workers: [
    {
      adapter: 'prisma',
      logger,
      queue: '*',
      count: 5,
      maxAttempts: 24,
      maxRuntime: 14_400,
      deleteFailedJobs: false,
      sleepDelay: 5,
    },
  ],
})
Now you have 5 workers. If you want to have separate workers working on separate queues, create another worker config object with a different queue name:
export const jobs = new JobManager({
  adapters: {
    prisma: new PrismaAdapter({ db, logger }),
  },
  queues: ['default'],
  logger,
  workers: [
    {
      adapter: 'prisma',
      logger,
      queue: 'default',
      count: 1,
      maxAttempts: 24,
      maxRuntime: 14_400,
      deleteFailedJobs: false,
      sleepDelay: 5,
    },
    {
      adapter: 'prisma',
      logger,
      queue: 'email',
      count: 1,
      maxAttempts: 1,
      maxRuntime: 30,
      deleteFailedJobs: true,
      sleepDelay: 5,
    },
  ],
})
Here, we have 2 workers working on the "default" queue and 1 worker looking at the "email" queue (which will only try a job once, wait 30 seconds for it to finish, and delete the job if it fails). You can also have different worker groups using different adapters. For example, you may store and work on some jobs in your database using the PrismaAdapter and some jobs/workers using a RedisAdapter.
We don't currently provide a RedisAdapter but plan to add one soon! You'll want to create additional schedulers to use any other adapters as well:
export const prismaLater = jobs.createScheduler({
  adapter: 'prisma',
})

export const redisLater = jobs.createScheduler({
  adapter: 'redis',
})
Job Errors & Failure
Jobs sometimes don't complete as expected, either because of an error in our code (unlikely, of course) or because a third party service that's being accessed responds in an unexpected way. Luckily, the job system is ready to handle these problems gracefully.
If you're using the PrismaAdapter and an uncaught error occurs while the worker is executing your perform function, three things happen:
- The job's
runAttime is set to a new time in the future, based on an incremental backoff computed from the number of previous attempts at running the job (attempts ** 4seconds, capped at 7 days) - The error message and backtrace is recorded in the
lastErrorfield - The job is unlocked so that it's available for another worker to pick up when the time comes
By checking the lastError field in the database you can see what the last error was and attempt to correct it, if possible. If the retry occurs and another error is thrown, the same sequence above will happen unless the number of attempts is equal to the maxAttempts config variable set in the jobs config. If maxAttempts is reached then the job is considered failed and will not be rescheduled. runAt is set to NULL, the failedAt timestamp is set to now and, assuming you have deleteFailedJobs set to false, the job will remain in the database so you can inspect it and potentially correct the problem.
Job Timeouts
A job that runs longer than the worker's maxRuntime is timed out: the worker stops waiting on it, records the timeout in the job's lastError, marks the job as failed and moves on to the next job. A timed-out job is not retried—the previous attempt could still be holding on to resources, so silently re-running it could mean two copies of the job doing work at once.
NodeJS Promises are not truly cancellable: you can reject early, but any Promises that were started inside will continue running unless they are also early rejected, recursively forever. So when a job times out, the worker can't forcefully kill your perform() function's promise—it can only stop waiting on it. This also means the timeout can only preempt asynchronous work: fully synchronous CPU-bound code blocks the event loop, so the timeout can't fire until it yields (and if such a job eventually returns, it completes normally).
To let your job actually stop working when it's timed out, an AbortSignal is available inside perform() via getJobExecutionContext(). It's aborted the moment the job exceeds maxRuntime. Pass it to fetch(), hand it to child processes you spawn, or check signal.aborted in long-running loops:
import { getJobExecutionContext } from '@cedarjs/jobs'

export const SampleJob = jobs.createJob({
  queue: 'default',
  perform: async (userId) => {
    const context = getJobExecutionContext()

    await fetch('https://example.com/expensive-thing', {
      signal: context?.signal,
    })
  },
})
The only way to guarantee a job will completely stop no matter what is for your job to spawn an actual OS-level process with a timeout (or the abort signal above) that kills it after a certain amount of time.
Deployment
For many use cases you may be able to rely on the job runner to start and detach your job workers, which will then run forever:
yarn cedar jobs start
When you deploy new code you'll want to restart your runners to make sure they get the latest source files:
yarn cedar jobs restart
Using this utility, however, gives you nothing to monitor that your jobs workers are still running: the runner starts the required number of workers, detaches them, and then exits itself. Node processes are pretty robust, but by no means are they guaranteed to run forever with no problems. You could mistakenly release a bad job that has an infinite loop or even just a random gamma ray striking the RAM of the server could cause a panic and the process will be shut down.
For maximum reliability you should take a look at the Advanced Job Workers section and manually start your workers this way, with a process monitor like pm2 or nodemon to watch and restart the workers if something unexpected happens.
Of course if you have a process monitor system watching your workers you'll want to use the process monitor's version of the restart command each time you deploy!
If you deploy with Baremetal, yarn cedar setup deploy baremetal generates a worker process for your monitor (a pm2 app or a systemd unit) when jobs are set up, and every deploy restarts it together with the app.
NODE_ENV
You'll need to explicitly set your NODE_ENV when in environments other than development or test. We like having a .env file in a serverfull production environment, and you just include:
NODE_ENV=production
If you're using Docker, make sure you have an ENV declaration for it:
ENV NODE_ENV="production"
Advanced Job Workers
As noted above, although the workers are started and detached using the yarn cedar jobs start command, there is nothing to monitor those workers to make sure they keep running. To do that, you'll want to start the workers yourself (or have your process monitor start them) using command line flags.
You can do this with the yarn cedar-jobs-worker command. The flags passed to the script tell it which worker group config to use to start itself, and which id to give this worker (if you're running more than one). To start a single worker, using the first workers config object, you would run:
yarn cedar-jobs-worker --index=0 --id=0
The job runner started with yarn cedar jobs start runs this same command behind the scenes for you, keeping it attached or detached depending on if you start in work or start mode!
Flags
--index: a number that represents the index of theworkersconfig array you passed to theJobManager. Setting this to0, for example, uses the first object in the array to set all config options for the worker.--id: a number identifier that's set as part of the process name. Starting a worker with--id=0and then inspecting your process list will show one worker running namedcedar-jobs-worker.queue-name.0. Usingyarn cedar-jobs-workeronly ever starts a single instance, so if your config had acountof2you'd need to run the command twice, once with--id=0and a second time with--id=1.--workoff: a boolean that will execute all currently available jobs and then cause the worker to exit. Defaults tofalse--clear: a boolean that starts a worker to remove all jobs from all queues. Defaults tofalse
Your process monitor can now restart the workers automatically if they crash since the monitor is using the worker script itself and not the wrapping job runner.
What Happens if a Worker Crashes?
If a worker crashes because of circumstances outside of your control the job will remain locked in the storage system: the worker couldn't finish work and clean up after itself. When this happens, the job becomes eligible for any worker to pick up and re-lock once maxRuntime (plus a one-minute grace period) has passed. A worker only takes back a job locked under its own lock name, which includes its host name and process id, so two running workers never take a job from each other.
Creating Your Own Adapter
We'd love the community to contribute adapters for Cedar Jobs! Take a look at the source for BaseAdapter for what's absolutely required, and then the source for PrismaAdapter to see a concrete implementation.
The general gist of the required functions:
find()should find a job to be run, lock it and return it (minimum return of an object containingid,name,path,argsandattemptsproperties)schedule()acceptsname,path,args,runAt,queueandpriorityand should store the job. Whatever it returns is returned fromlater(), so return at least an object with the stored job'sidso users can cancel it or check on it latersuccess()accepts the same job object returned fromfind(), arunAtdate and adeleteJobboolean for whether the job should be deleted upon success.runAtis set for recurring (cron) jobs: store it as the job's next run time and reset the job'sattemptsto 0.error()accepts the same job object returned fromfind()and an error instance. Does whatever failure means to you (like unlock the job and reschedule a time for it to run again in the future)failure()is called, instead oferror(), when the job has reachedmaxAttemptsor exceededmaxRuntime. Accepts the job object, adeleteJobboolean that says whether the job should be deleted, and theerrorof the failed attempt, which should be recorded in the same write that marks the job as failed.clear()remove all jobs from the queue (mostly used in development).supportsUniqueKeys(optional) set it totrueifschedule()honors the payload'skey: while a job with that key is queued it must not add another one. Scheduling with akeythrough an adapter without it throws aUniqueKeysNotSupportedError.syncSchedules()(optional) accepts the declaredschedules(each aschedule()payload with acronand akey) and akeyPrefix, and makes the stored schedules match them: create missing ones, update changed ones and remove stored ones with a key starting withkeyPrefixthat aren't declared. Several workers call it at once, so it must not create duplicates. Without it, jobs can't declareschedules.cancel()(optional) accepts an object with ajobIdproperty and should make sure that job never runs (or is never retried, if it's currently running). Returntrueif a job was cancelled,falseotherwise. If you don't implement this function,later.cancel()will throw aCancelNotImplementedError.pause()andresume()(optional) accept an object with ajobIdproperty. A paused job must not be returned byfind(), and must stay paused whensuccess()orerror()reschedule a run that was in progress.resume()gives a recurring job its nextrunAtat the next match of its cron from now, and leaves a one-off job'srunAtalone. They return{ alreadyPaused, pausedAt }and{ wasPaused, runAt }, and throw aJobIdNotFoundErrorfor an unknown id and aJobNotActiveErrorfor a job that has completed or failed for good. Without them,jobs.pauseJob()andjobs.resumeJob()throw aPauseNotImplementedError.list()(optional) accepts an object with alimit, and optionallyqueuesandpaused: true(which a starting worker uses to warn about paused jobs), and returns the jobs that are waiting to run, running or paused, the ones that run next first, each with itsid,name,queue,cron,runAt,pausedAt,attemptsand whether it'srunning. Used byyarn cedar jobs list.
The Future
There's still more to add to background jobs! Our current TODO list:
- More adapters: Redis, SQS, RabbitMQ...
- CedarJS Admin integration: monitor the state of your outstanding jobs, cancel or retry jobs from a UI, read failure logs, and more.
- Lifecycle hooks:
beforePerform(),afterPerform(),afterSuccess(),afterFailure() - Let us know what you need! https://cedarjs.com/discord